Tokenizer
Parse a Schematika character stream into lexical tokens
Context
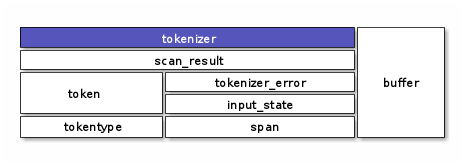
#include <xo/tokenizer/tokenizer.hpp>
Assemble a stream of lexical tokens from a text stream.
Lexical errors reported via scan_result instance; errors reported with detailed context
Class
-
template<typename CharT>
class tokenizer Parse a Schematika character stream into lexical tokens.
Use:
// see xo-tokenizer/example/tokenrepl/tokenrepl.cpp
// for exact working code

using tokenizer_type = tokenizer<char>;
using span_type = tokenizer_type::span_type;

tokenizer_type tkz;
span_type input = ...;

while (!input.empty()) {
    auto [tk, consumed, error] = tkz.scan(input);

    if (tk.is_valid()) {
        // do something with tk
    } else if (error.is_error()) {
        error.report(cout);
        break;
    }

    input = tkz.consume(consumed, input);
}

if endofinput {
    auto [tk, consumed, error] = tzk.notify_eof()

    // do something with (final) tk if tk.is_valid()
}
See tokentype.hpp for token types
Instance Variables
- group tokenizer instance variables
Variables
-
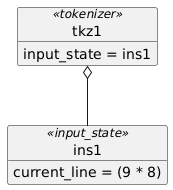
input_state_type input_state_
track input state (line#,pos,..) for error messages. There’s an ordering problem here:
input_state_.skip_leading_whitespace() advances current line automagically when it sees
need to capture value of input_state_ before newline
but neeed newline to end token Also recall input_state_type needed for reporting errors.
-
std::string prefix_
Accumulate partial token here. This will happen if input sent to tokenizer::scan ends without whitespace such that last available token’s extent is not determined
-
input_state_type input_state_
Constructors
- group tokenizer constructors
Functions
-
tokenizer(bool debug_flag = false)
-
tokenizer(bool debug_flag = false)
Methods
- group tokenizer methods
Functions
-
static bool is_1char_punctuation(CharT ch)
identifies punctuation chars. These are chars that are not permitted to appear within a symbol token. Instead they force completion of a preceding token, and start a new token with themselves
-
static bool is_2char_punctuation(CharT ch)
more-relazed version of is_1char_punctuation. Chars that are not permitted to appear within a symbol token, but may form token combined with next character
-
static result_type assemble_token(std::size_t initial_whitespace, const span_type &token_text, input_state_type &input_state)
assemble token from text
token_text.initial_whitespaceAmount of whitespace input being consumed from input.token_textsubset of input_line representing a single token.input_stateinput state containing input_lineretval.consumed will represent some possibly-empty prefix of
input
-
static result_type assemble_final_token(const span_type &token_text, const input_state_type &input_state)
degenerate version of assemble_token() on reaching end-of-file
-
inline bool has_prefix() const
true if tokenizer contains stored prefix of possibly-incomplete token
-
result_type scan(const span_type &input, bool eof_flag)
scan for next input token, given
input. Note:tokenizer can consume input (e.g. whitespace) without completing a token
input will remember the extent of the last line of input for which parsing has begun, but not completed. It’s required that at least that portion of the input span remain valid across scan(), scan2() calls
- Returns:
{parsed token, consumed span}
-
void discard_current_line()
discard current line after error. Just cleans up error-reporting state
-
static bool is_1char_punctuation(CharT ch)